 SageVoice
Frequently asked questions
Who runs SageVoice?
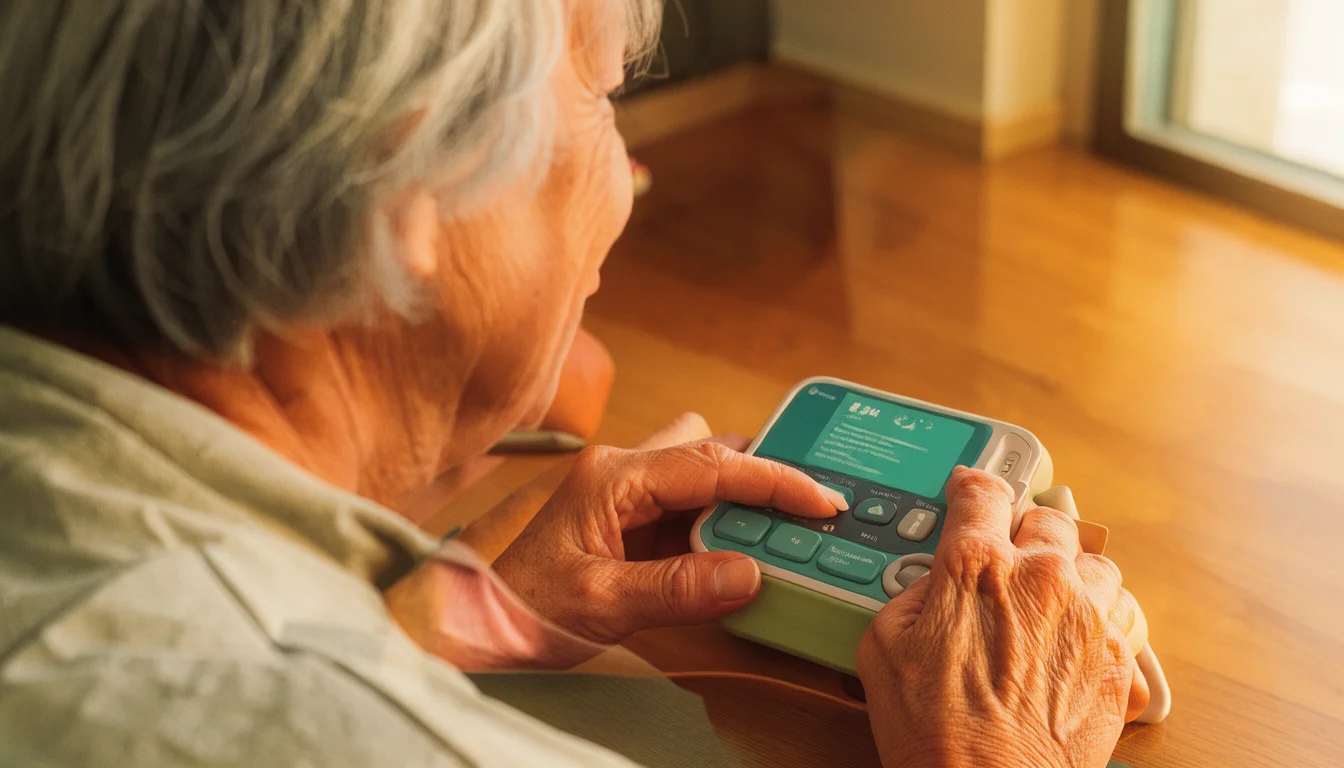
SageVoice is an independent storefront for a cloud text-to-speech API, designed specifically for non-technical users and assistive device makers. We operate as a standalone service, not affiliated with major tech brands, focusing on transparent pricing and reliable audio generation for elderly care and accessibility tools without requiring complex coding knowledge.
How are the voices licensed?
Our eight voice presets are based on licensed recordings from LibriTTS-R (CC BY 4.0) and public-domain audiobook readings from LibriVox. This ensures high-quality, natural speech while maintaining clear licensing standards. Each generated audio file also contains an inaudible watermark to clearly mark it as synthetic speech for transparency.
Is my data safe with SageVoice?
Input text is used solely to produce the audio and is not used for training models. Generated audio is returned in the response and not stored. We keep request metadata, such as time, characters, and status, only for billing purposes, ensuring your data remains private and secure during processing.
What are the limitations of SageVoice?
We do not offer streaming, SSML, custom voice cloning, or our own SDK. We do not offer phone support. There is no SLA, uptime guarantee, or phone support. Requests are limited to 60 per minute, and text input is capped at 4096 characters per request. We support 23 languages but do not offer real-time partial audio delivery.
How can I contact SageVoice?
Support is available exclusively via email. We do not offer live chat, phone support, or on-site assistance. For technical issues or billing questions, please reach out through the contact page on our website. We aim to provide helpful, direct answers to assist you with your accessibility projects efficiently.
Does SageVoice have a phone number?
No, SageVoice does not have a phone number. All support is handled through email to keep operations streamlined and cost-effective for our API users. This allows us to maintain transparent pricing and focus on delivering reliable text-to-speech services for assistive devices without the overhead of traditional phone support channels.
What is the response time for support?
Since support is email-only, response times may vary depending on volume. Please ensure your inquiry includes relevant details like your API key and error logs to help us resolve your issue as quickly as possible.
Are the voices real people or synthetic?
The voices are synthetic, generated from licensed recordings. Each file carries an inaudible watermark marking it as synthetic speech. While the source material comes from human readings, the output is AI-generated, ensuring consistent quality and flexibility for your accessibility tools without requiring ongoing licensing for individual voice actors.
Our Mission
SageVoice provides a straightforward text-to-speech API designed specifically for non-technical users and assistive device makers. We simplify voice generation so you can produce clear, natural audio without managing complex code or infrastructure, making accessibility tools easier to deploy.
Simplifying TTS for Everyone
Our API works like sending a text message: you send text, and receive an audio file. This simplicity helps elderly care providers and accessibility tool developers integrate voice capabilities quickly, focusing on user experience rather than technical details.
Supporting Assistive Tech
We focus on delivering reliable, clear speech for assistive devices. Our voices are optimized for readability, ensuring that users with visual or cognitive impairments can consume content comfortably. The API supports 23 languages, covering most major communication needs.
Transparent and Honest
We avoid hype and false claims. Our pricing is simple: $10 per million characters. You know exactly what you pay for, with no hidden fees or complex tiers. We list our limitations clearly, so you can plan your project accurately.
Who We Are
We noticed that many non-technical users and makers of assistive devices struggled with complex TTS implementations. Our goal is to bridge that gap by providing a simple, reliable API that works like sending a text message.
Editorial Team Background
We focus on clarity and honesty in every detail, ensuring that the API documentation is easy to follow without requiring a developer degree.
Focus on Non-Technical Users
We designed SageVoice for those who need clear speech but lack coding expertise. The API mirrors the familiar OpenAI structure, allowing you to use existing tools or simple scripts. We prioritize straightforward integration so you can generate audio without managing complex infrastructure.
- Simple JSON requests
- No complex SDKs required
- Clear pricing structure
Industry Expertise
We understand the specific needs of assistive device makers. Our voices are selected for clarity and naturalness, crucial for elderly users who may have hearing impairments. We ensure the audio quality is consistent and reliable for daily use in care settings.
Voice Licensing
Every voice in our library is based on licensed recordings from the LibriTTS-R dataset, ensuring clear and reliable synthetic speech for assistive devices. This approach provides a consistent audio quality without the complexity of custom voice design or expensive celebrity licensing agreements.
LibriTTS-R License
We utilize the LibriTTS-R dataset, which contains high-quality speech recordings specifically curated for text-to-speech research and development. This foundation ensures that our 8 voice presets deliver natural, clear audio suitable for elderly care and accessibility tools.
- Based on established, high-quality speech datasets
CC BY 4.0
The underlying audio data is licensed under Creative Commons Attribution 4.0 International. This transparent licensing model allows us to pass clear usage rights to our API consumers, ensuring you can integrate these voices into your assistive applications without hidden legal complexities.
- Open and transparent licensing terms
Public Domain Sources
Our voices are derived from LibriVox public-domain audiobook readings. These recordings are free from restrictive copyright claims, allowing us to offer consistent pricing and reliable service for non-technical users building accessibility solutions without worrying about ongoing royalty fees.
Data Privacy Policy
We treat your data with respect. When you send text to our API, it is processed solely to generate the audio file you receive. Once the audio is delivered, we do not store the generated audio content itself.
Our approach is straightforward: we use your input only for the immediate task of synthesis. This ensures that your content remains private and is not repurposed for other uses outside your specific request.
Text Used Only for Generation
Input text is used exclusively to produce the audio file returned in the response. We do not archive or repurpose your specific text content after synthesis is complete.
This means your unique phrases, stories, or instructions are not retained in our long-term storage systems. The audio you receive is generated on-demand and delivered directly to you.
No Training on Data
We do not use your input text or generated audio to train our models or improve the API for other customers. Your data remains yours.
This policy applies to all users, ensuring that your specific content does not influence the voices or engine behavior for other accounts.
Secure Storage
We keep request metadata, such as timestamp, character count, and status, strictly for billing and usage tracking. This minimal data ensures accurate charging based on the $0.01 per 1,000 characters rate.
These records are stored securely and are used only to verify that your account balance reflects your actual usage. No personal identifiers are linked to this metadata beyond your account key.
Honest Limitations
We believe in clarity about what our API can and cannot do. This helps you plan your assistive device workflows accurately without unexpected surprises during deployment.
No Streaming Support
Our API returns the complete audio file after synthesis finishes. It does not support streaming or WebSocket connections for real-time partial audio. For assistive devices, you must wait for the full file to download before playback begins.
No Custom Voice Cloning
We do not offer custom voice cloning or uploading your own voice samples. You must choose from our eight licensed presets like Aria or Atlas. These voices are based on LibriTTS-R recordings and carry an inaudible synthetic watermark.
Email Support Only
Our team provides support exclusively via email. We do not have a phone number or live chat widget on this site. Please check your inbox for responses regarding your API key or billing questions.
Contact Us
We believe that clear communication starts with a simple, direct line. Our support team is here to help you integrate SageVoice into your assistive devices or elderly care tools without unnecessary friction.
Email Support
All inquiries are handled via email. This allows us to keep a clear record of your technical questions and billing details, ensuring nothing gets lost in translation. You can reach us at [email protected] for any questions about the API, pricing, or voice selection.
No Phone Number
We do not offer a phone number. This decision reduces overhead and keeps our pricing transparent for you. If you prefer asynchronous communication, email is the most reliable way to get detailed answers without waiting on hold.
Response Time
We strive to respond to all emails within 24 hours during business days. Since we are a small team focused on engineering, we prioritize thorough answers over quick replies. For urgent billing issues, please include your API key in the subject line.
Listen to the 8 voices
Each sample below was generated by this API from the same sentence. The voice should sound warm and clear, avoiding harsh or monotone delivery that can cause listener fatigue over extended use.


23 languages
Any voice speaks any of these languages.
